

Other2 months ago
FlexInference: Drop your AI costs today
Route your LLM API requests across multiple providers to cut costs and meet latency targets.
Aperswal · HN
Made a Free LLM Router
The full gallery
Tech stack
21 projects
Route your LLM API requests across multiple providers to cut costs and meet latency targets.
Aperswal · HN
Made a Free LLM Router
Route LLM calls to cost-effective models without sacrificing quality.
george_avila · Product Hunt
IQ Routing Trajectory-aware LLM routing that cuts agent cost

Automatically route each prompt to the cheapest capable model to cut API costs.
u/ASDKING100 · Reddit
Launched an AI API router tonight, and found a bug hours in that would've taken real payments without ever upgrading the account Built LLMLite over the past few weeks — it classifies each prompt and routes it to the cheapest model that can actually handle it, instead of hitting GPT-4o for everything. Free tier, no card needed to try it. Tonight, right as I was about to launch, ran a real transaction to test the payment flow end to end. Paddle processed it, webhook fired, signature verified
Format-agnostic LLM hub. Bring your own provider keys and route across Anthropic, OpenAI, ChatGPT/Codex, Kimi, Alibaba DashScope, and AWS Bedrock — with unified observability and c

@0xxmemo · X
Run deterministic LLM queries using open-weight models like Gemma 4 at low cost.
carsonpoole · HN
Determinstic LLM inference for lowest price Gemma 4, with Windows XP

Route requests to Claude, GPT, Codex and more through a single OpenAI-compatible API.

@RouteraOne · X
daily limits turning vibe coding into handless mode 😭 Routera gives you usage-based access to Claude, Codex, GPT and more, without daily or weekly caps, and it’s usually cheaper than stacking subscriptions
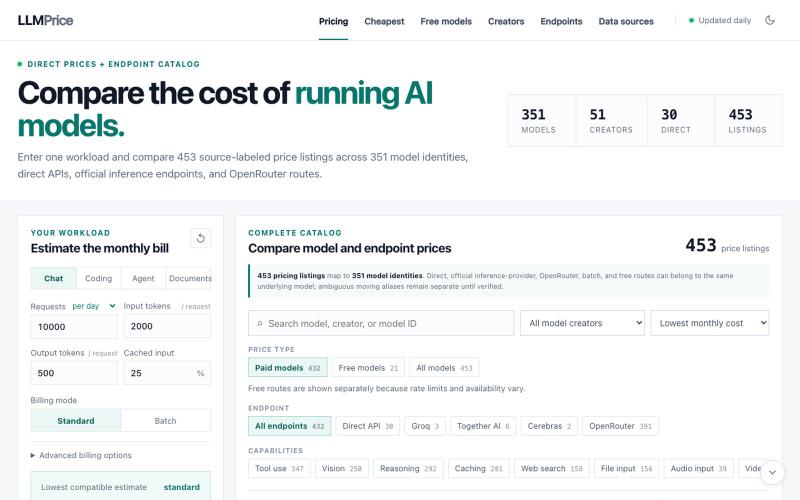
Compare LLM API pricing across 450+ routes and calculate real monthly costs with caching and batch pricing factors.
u/Greywolff06 · Reddit
I built LLMPrice — a free calculator for comparing LLM API costs across 450+ pricing routes I kept running into the same problem when comparing LLM APIs: the headline token price doesn't always tell you what your actual workload will cost. Caching, batch pricing, reasoning tokens, retries, different endpoints, and OpenRouter routes can change the result quite a bit. So I built LLMPrice.com. You enter your workload once — requests, input/output tokens, caching, retries, etc. — and it com
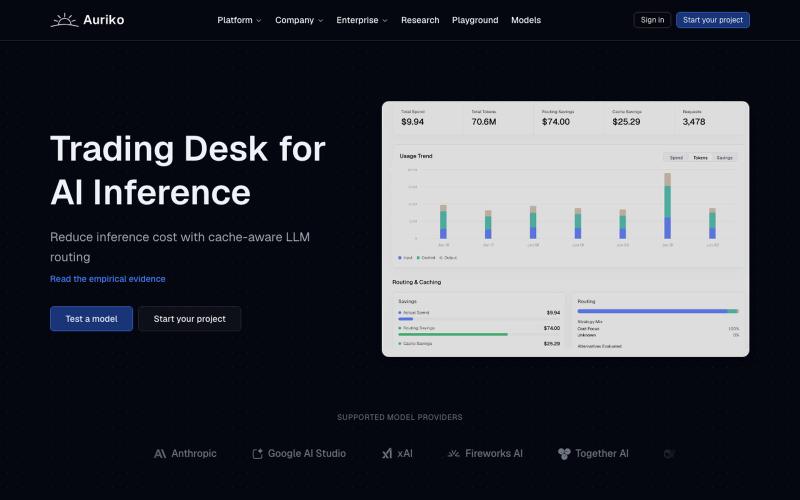
Use one API to access and switch between LLM providers while optimizing inference costs.
justin2025 · Product Hunt
Auriko Trading desk for LLM calls

Tests LLM endpoints with adversarial cases and provides OWASP-mapped security audit reports.

@aryaan_sheth · X
- LLM security for small teams
AI assistant that learns your workflow and routes coding tasks across 30+ frontier models.

@otakuaakash · X
Semantic caching reduces LLM token costs and latency for AI queries.
u/ornymo_official · Reddit
how to reduce ai costs there are lots of way to reduce costs but there all complex to setup i know this cause i tried one in production so i built ornymo we cache meaning not the exact string allowing us to give same awnsers thus reducing llm costs and latency check it out at ornymo.com free for a limited time and let me know your feedback submitted by /u/ornymo_official to r/buildinpublic [link] [comments]
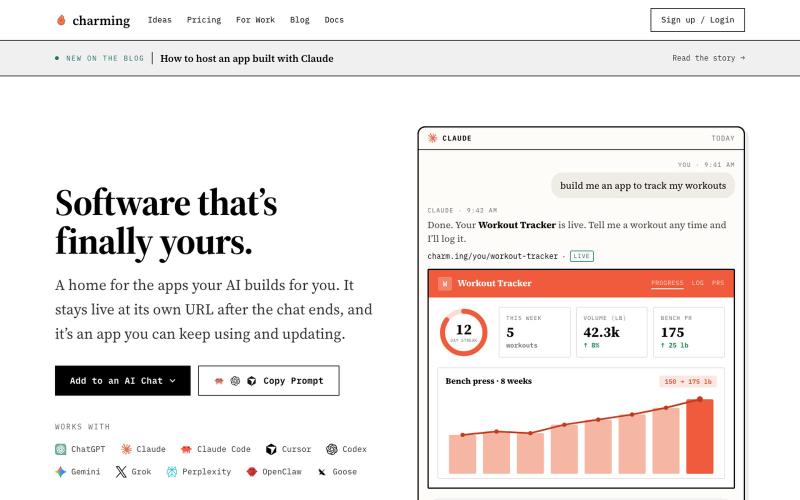
Build and host AI-powered applications with data storage and persistent URLs.

@akhileshrangani · X
i built codex micro and used it inside of claude to control codex AND claude code it uses a herdr bridge that is running on my mac talks it through a ngrok proxy uses to render inside of claude