

Other2 months ago
FlexInference: Drop your AI costs today
Route your LLM API requests across multiple providers to cut costs and meet latency targets.
Aperswal · HN
Made a Free LLM Router
The full gallery
Tech stack
60 projects
Route your LLM API requests across multiple providers to cut costs and meet latency targets.
Aperswal · HN
Made a Free LLM Router
Route LLM calls to cost-effective models without sacrificing quality.
george_avila · Product Hunt
IQ Routing Trajectory-aware LLM routing that cuts agent cost
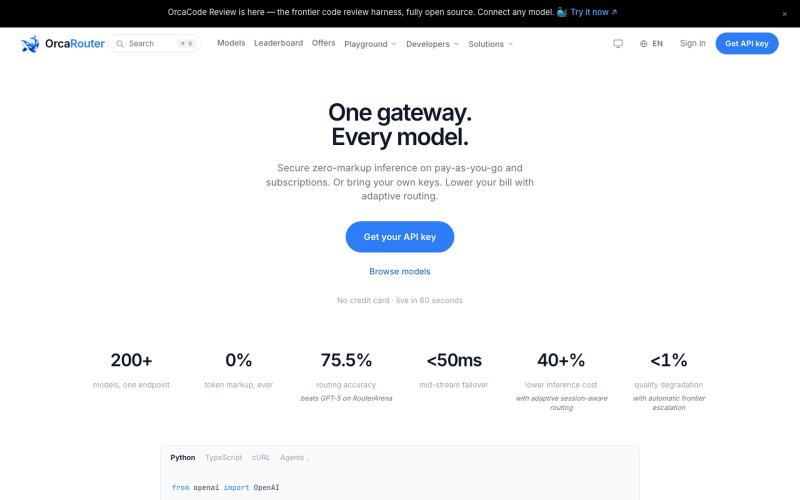
Adaptively route and load-balance requests across 200+ LLMs through one OpenAI-compatible gateway.
Continuum-AI-Corp · GitHub
OrcaReplay OrcaReplay — Time travel for AI agents. Record, replay, fork, and debug any agent run with any model. Built by the OrcaRouter.ai team.

Automatically route each prompt to the cheapest capable model to cut API costs.
u/ASDKING100 · Reddit
Launched an AI API router tonight, and found a bug hours in that would've taken real payments without ever upgrading the account Built LLMLite over the past few weeks — it classifies each prompt and routes it to the cheapest model that can actually handle it, instead of hitting GPT-4o for everything. Free tier, no card needed to try it. Tonight, right as I was about to launch, ran a real transaction to test the payment flow end to end. Paddle processed it, webhook fired, signature verified
Kryvlo is the intelligent LLM gateway that routes every prompt to the right model automatically. Build no-code Routing Strategies, clone Community Strategies, and cut LLM costs up

@xblasters300 · X
Self-hosted LLM control plane for managing API gateway traffic across providers like LiteLLM and Bifrost.
siva_prakash_kumar · Product Hunt
Agnos LLM gateway Contain LiteLLM, Bifrost, Portkey.. behind one control plane
Format-agnostic LLM hub. Bring your own provider keys and route across Anthropic, OpenAI, ChatGPT/Codex, Kimi, Alibaba DashScope, and AWS Bedrock — with unified observability and c

@0xxmemo · X

Route LLM API traffic through a gateway with built-in cost tracking, latency analytics, and PII redaction.
charltonraven · HN
RavenGate – LLM gateway that redacts PII across SSE chunk boundaries

Route requests to Claude, GPT, or GLM through one API key with free daily credits.

@Awais_209 · X
Claude Opus 4.8, GPT-5.5 & GLM-5.2 for free. Get $25/day in credits. No trial or waitlist. One API key works with Claude Code, Cline, Cursor, Roo & OpenAI-compatible tools. Try it: #FreeTier #ClaudeAPI #CodingTools @AgentRouter_0
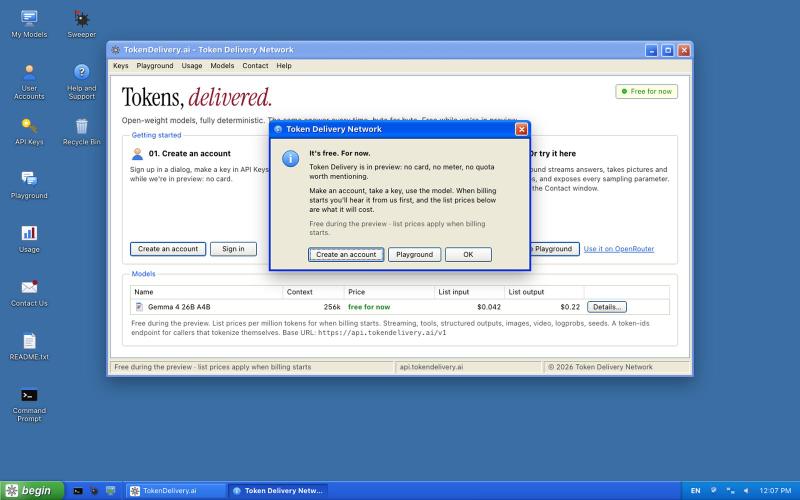
Run deterministic LLM queries using open-weight models like Gemma 4 at low cost.
carsonpoole · HN
Determinstic LLM inference for lowest price Gemma 4, with Windows XP

Route requests to Claude, GPT, Codex and more through a single OpenAI-compatible API.

@RouteraOne · X
daily limits turning vibe coding into handless mode 😭 Routera gives you usage-based access to Claude, Codex, GPT and more, without daily or weekly caps, and it’s usually cheaper than stacking subscriptions
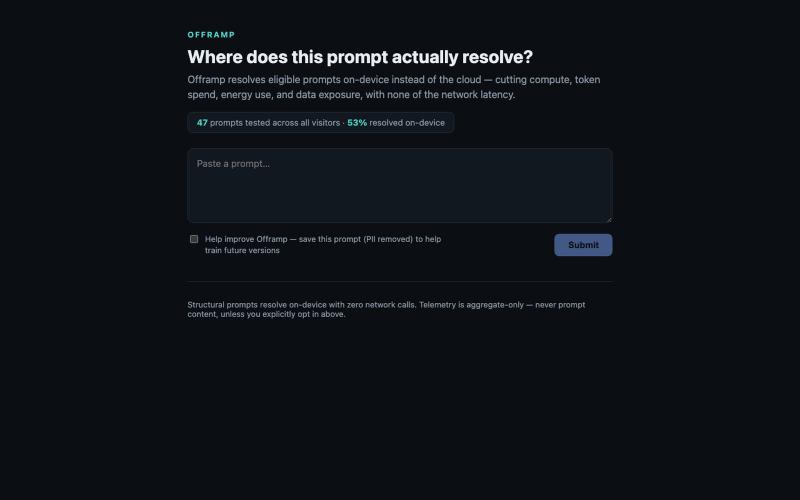
SDK that routes LLM prompts locally when possible to reduce cloud API costs.
u/econobro · Reddit
Built a tool that skips the cloud LLM call when the prompt doesn't need one — would love feedback Live demo, no login, paste anything and see where it actually resolves and why: link What I built Offramp — a small client-side SDK that sits in front of whatever LLM API call your app already makes, and resolves some prompts entirely on-device instead of sending them to Claude/GPT/whatever cloud model you're using. Yes, I used Claude (you'll be able to tell right away if yo