
Creative Tools2 weeks ago
UUZP · 让出片更简单
Quickly curate hundreds of photos in your browser using local, privacy-focused processing.
alexmaster · V2EX
玩摄影,选片神马的最烦,于是搞了个选片工具 uuzp.cn 每次拍完照片都是几百张,选片最烦人了。 当然隐私更重要,本地处理,无上传。 纯浏览器端处理。 https://uuzp.cn 欢迎大家使用
The full gallery
Tech stack
60 projects
Quickly curate hundreds of photos in your browser using local, privacy-focused processing.
alexmaster · V2EX
玩摄影,选片神马的最烦,于是搞了个选片工具 uuzp.cn 每次拍完照片都是几百张,选片最烦人了。 当然隐私更重要,本地处理,无上传。 纯浏览器端处理。 https://uuzp.cn 欢迎大家使用

File-first memory runtime for AI agents with dashboard and HTTPS API access.

@memofsdev · X
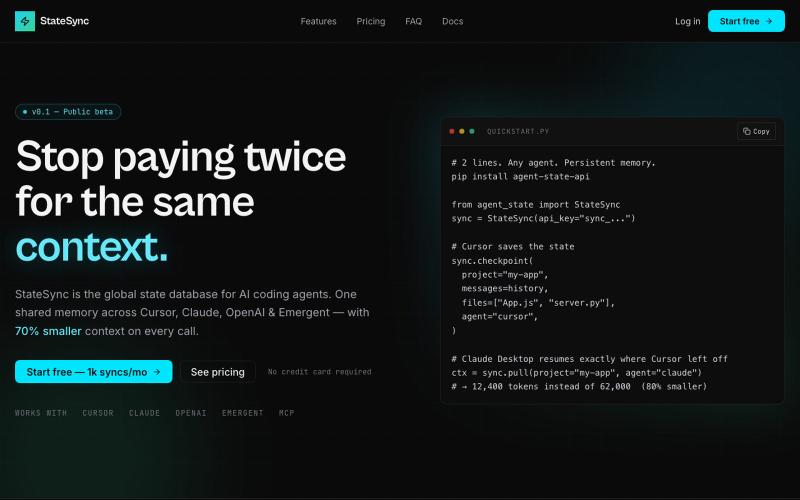
Prevent context loss and AI agent amnesia. StateSync provides real-time state persistence and agent handoffs over MCP.

@StateSync_ · X

Mask personal data and reduce AI token costs by processing data locally before sending to Claude, ChatGPT, Gemini, or other APIs.

@AI_303030 · X
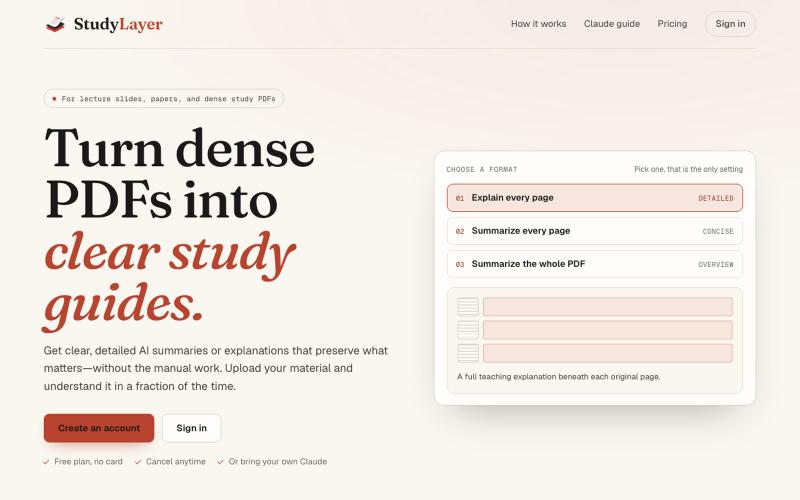
Turn lecture PDFs into smart study notes with visual page references.
u/Leanna_Every · Reddit
I built StudyLayer after spending days turning lecture slides into useful notes https://reddit.com/link/1w20w3d/video/kbizu752cemh1/player I’m an undergrad student, and I built StudyLayer to solve my own problem. When I uploaded an entire lecture PDF to a general AI chat, the explanation was often too generic and inconsistent. Important details could be lost. My workaround was painful. Take a screenshot of one page, paste it into the chat, request an explanation, copy the response into

Save multimedia content and turn it into searchable summaries and flashcards powered by AI.

@ShahirSiddiqu13 · X
Memora turns everything you save into a searchable second brain powered by AI. Try it: 🌐 What would you save first? #BuildInPublic #SaaS #AI #Productivity

Design, simulate, and learn engineering projects from Arduino circuits to Mars rovers.

@piyushh_216h · X
Check out what I just built with Lovable! UES (Universal Engineering System) is an AI-powered multilingual engineering platform where students, engineers, researchers, and innovators can learn, build. Thank's spacex. @SpaceX @elonmusk .@sky
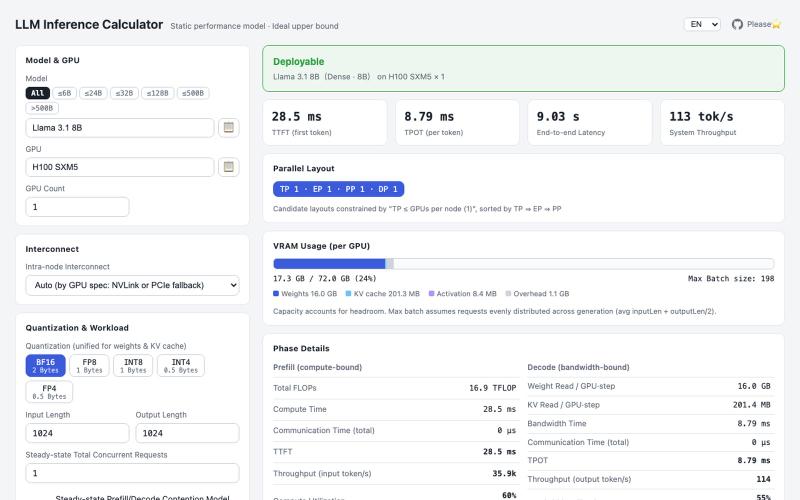
Estimate GPU memory, latency, TTFT, TPOT, and throughput for LLM inference.
popopanda · HN
LLM Inference Calculator – Estimate VRAM, Latency, and Throughput
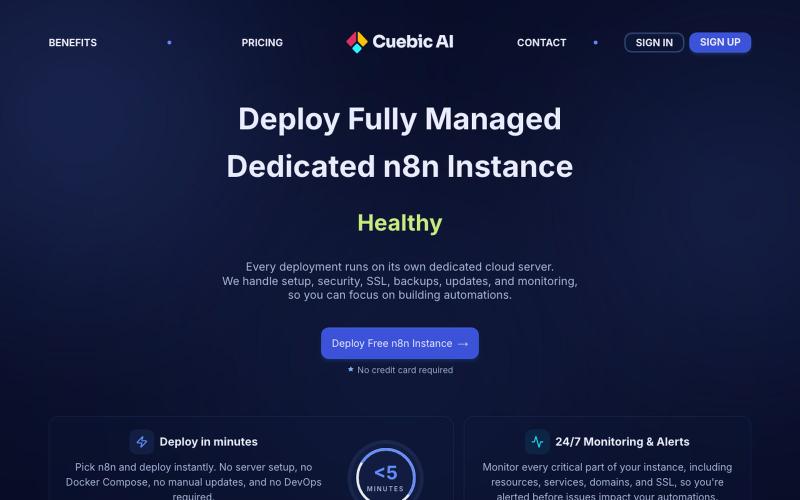
Deploy your own secure, production-ready n8n instance in minutes with built-in 24/7 monitoring, email alerts, SSL, custom domains, and backups. Free 1-week trial.

@cuebicai · X
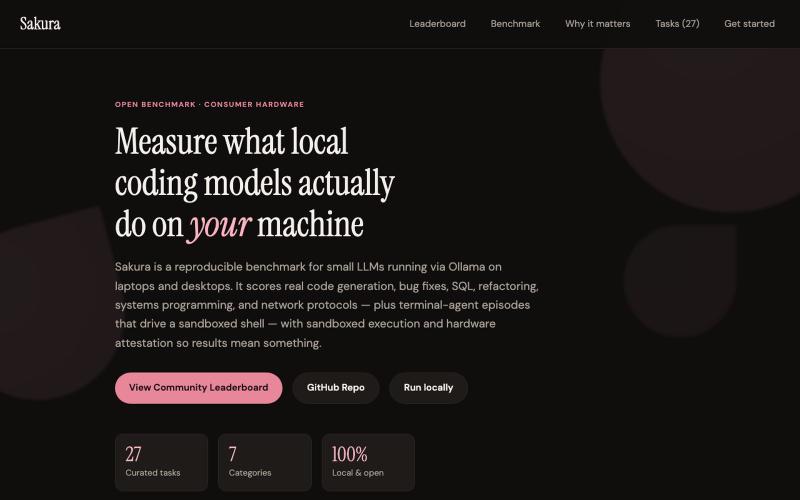
Benchmark local coding models on consumer hardware to measure accuracy, latency, and throughput across 27 tasks.
u/Unfair_Association89 · Reddit
I built a reproducible benchmark for local coding models (Ollama, 27 tasks, live leaderboard) ran it on my 8GB card, here's what I found I kept eyeballing "vibes" to decide whether one quant of a coding model was actually better than another on my machine, so I built Sakura to get real numbers instead. What it does: - Points at any Ollama model and runs it through 27 hand-curated tasks: codegen, bugfix, SQL, refactor, systems design, protocol implementation, and terminal-agent episode
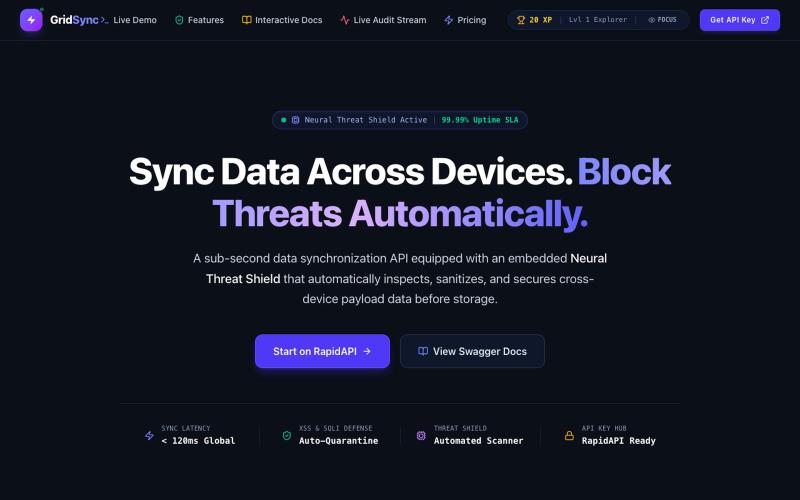
Sync data across devices in real-time with automatic security inspection via an API.

@mygridsyncdev · X
Just launched GridSync ⚡️ Sub-150ms zero-trust payload inspection & real-time sync for modern APIs. Try the free tier on RapidAPI or check out the docs: #buildinpublic #API #FastAPI

Core keeps your integrations, files, and preferences available across every AI tool you use.

@figueredoc_ · X