
Developer Tools3 weeks ago
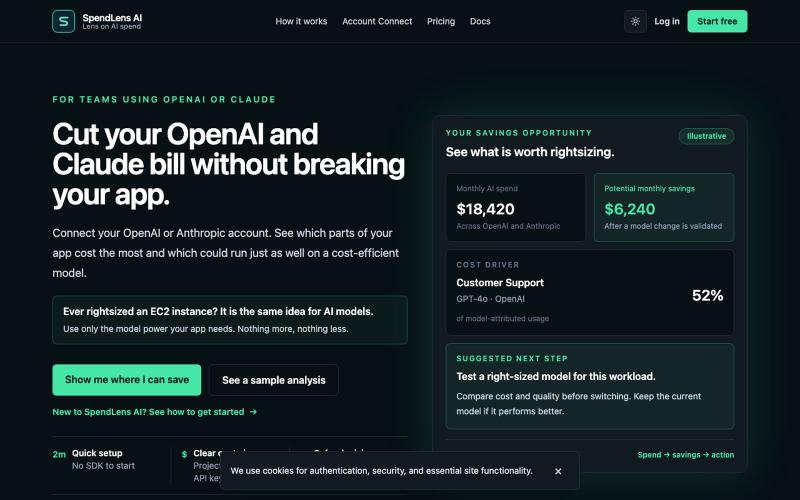
AI Model Rightsizing for OpenAI and Anthropic | SpendLens AI
Analyze AI spending from OpenAI and Anthropic APIs, then validate cheaper models without recoding.

@SpendLensAI · X
The full gallery
Tech stack
61 projects
Analyze AI spending from OpenAI and Anthropic APIs, then validate cheaper models without recoding.
@SpendLensAI · X

Compare AI system outputs against baselines to detect performance regressions.

@JustinGarr90748 · X
We're building Cyberelf labs because a better score doesn't mean a better model.
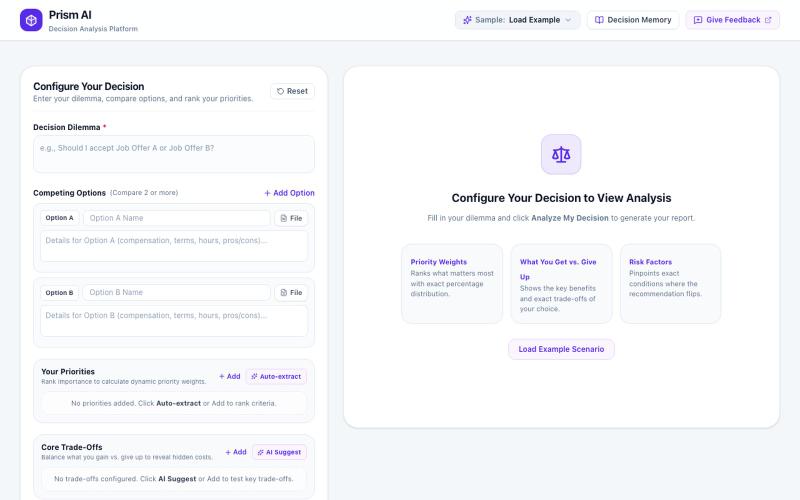
Cognitive trade-off modeling and high-stakes decision intelligence engine.

@PrismAI_HQ · X
Make smarter decisions by seeing the trade-offs clearly. That’s Prism AI, an AI decision tool for when you’re stuck choosing between options. On Product Hunt Aug 29
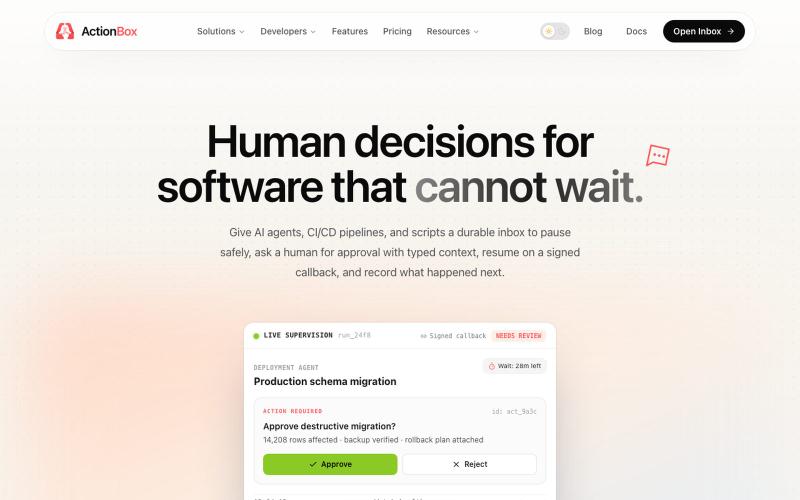
Human approval layer for AI agents, scripts, and CI/CD pipelines.
u/king4queen · Reddit
Human Approval (HITL) for AI and autonomous system. I kept running into the same annoying problem with scripts and automations: Everything works fine until the software needs a human. Then suddenly I’m building the same stuff again: send a Slack/email notification save some pending state wait without losing the workflow show enough context to make a decision approve/reject/answer something somehow send that answer back handle retries, timeouts and duplicates So I start

Test AI agents against production mirrors using replayed traces to find bugs and regressions.
aisinghal
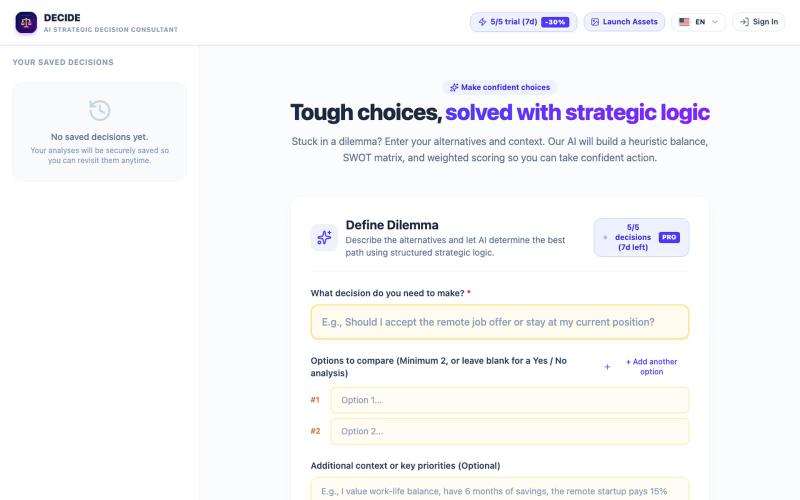
Make better decisions with AI analysis of pros/cons, comparisons, and SWOT frameworks.
angel_villanueva2 · Product Hunt
DECIDE Solve hard dilemmas with AI & decision logic

Scan and monitor AI-coded apps for security, performance, and code quality issues.

@Vibedoctor_io · X
Connect VibeDoctor MCP to Cursor, Copilot, Claude Code or Windsurf. Your agent gets a security gate built in. #ClaudeCode #AppSecurity #DevTools
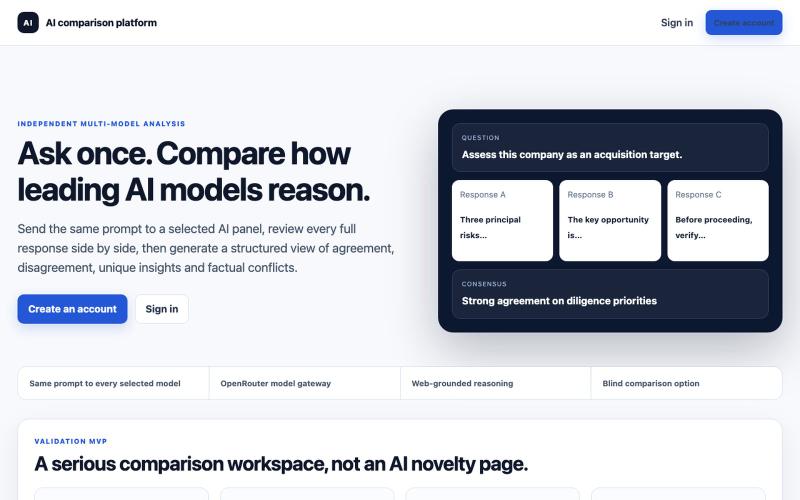
Ask multiple leading AI models the same question and compare their answers side by side.

@christosag · X
🚀 Pre-Seed | MVP Validation ⚡ Multiple MVPs live - with more continuously shipping. 🔎 RAG - verifiable doc search 🏥 Health - scheduling 🤖 AI Compare - consensus 🏗️ Builder Scrutiny - contract intel 🤝 Angels + Pre-Seed VCs welcome

Ask one question to multiple AI models, compare their answers, and watch them debate to consensus.
u/trekhleb · Reddit
I kept pasting the same question into ChatGPT, Claude, and Gemini in three tabs; so I built a Yes-Brainer — a council of AI models, that answer your question in parallel, debate to consensus, or get judged to a verdict. submitted by /u/trekhleb to r/SideProject [link] [comments]

Analyzes AI prompts to identify failures and return corrected versions.
u/pulptaken · Reddit
I built a website to audit AI prompts I'm giving away a limited number of early access invites for anyone who wants to try Marzel. You'll also be able to try the product once directly from the landing page, without joining the early access. This initial phase is focused on validating the core features and collecting feedback. After that, Marzel will also include a browser extension and a desktop app for auditing Claude Code and Codex CLI sessions, which is the project's main goal. If yo

Analyze how your brand appears in AI search engines like SGE, ChatGPT, and Perplexity.
u/No_Pangolin3678 · Reddit
We built AiVisis to measure brand visibility in AI search — looking for honest feedback Hi r/SideProject , I’m part of the team building AiVisis, a GEO and AI visibility analysis platform for businesses, marketers, and agencies. Most companies already track their search rankings, website traffic, and social media performance. However, many brands still cannot clearly answer a newer question: How visible is our brand across AI-powered search and answer platforms? AiVisis analyzes a we

Propose actions and watch an AI control plane evaluate policies, handle approvals, execute, and verify results in real-time.
eli-labz · GitHub
Agent-Execution-Partnership Agent Execution Partnership AEE is an open-source control plane that ensures every AI agent action is authorized before it runs, observable while it runs, and verifiable after it completes.